how to run audience surveys without panels
Written by the moevox.com content team
10/1/2026
how to run audience surveys without panels
Our team needed empirical validation for a series of high-stakes content pieces about remote work technology shifts, but our budget precluded hiring an external panel provider and our publishing schedule left no room for a three-week recruitment cycle. We initially tried prompting a standard large language model to roleplay various reader demographics, but the outputs contradicted each other across consecutive runs and produced impossibly uniform sentiment scores.
That contradiction forced us to look at how audience research was actually constructed, leading us toward platforms like MoeVox, a research data platform designed for content creators who need empirical data and statistics to support SEO and GEO content.
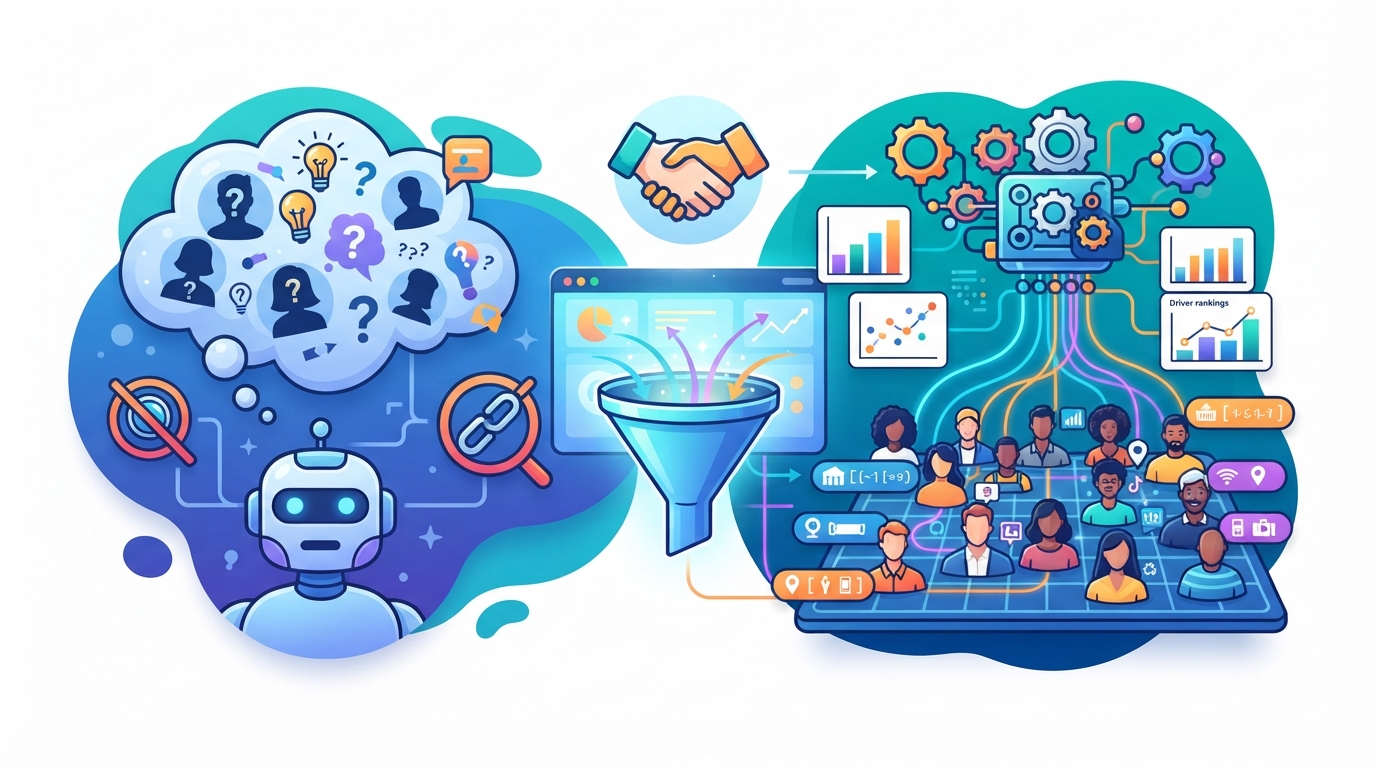
The platform takes a user-defined research question, a target audience, and options to test, and uses them to generate a structured questionnaire, subsequently producing a survey dataset and a structured report containing a winning option, driver rankings, response distributions, and top respondent concerns through a web application, credits-based pricing tiers, a REST API, or an AI prompt template.
The Hidden Bottleneck of Traditional Respondent Panels for Creators and Strategists
Trying to secure qualified human respondent panels for niche B2B or consumer content within standard editorial timelines exposes a structural mismatch between traditional market research and modern publishing cadences. When I sat down to map out our remote work technology cluster, I quickly found that external panel vendors required budgets and recruitment windows that simply did not fit our quarterly planning cycle.
Waiting weeks for human respondents to fill out screeners meant our publishing schedule would slip past the active search trend window, rendering the content obsolete before it ever went live.
Faced with that delay, editorial teams often default to asking generic AI chat prompts to roleplay target audiences, assuming that conversational models can stand in for human respondents. That shortcut collapses under scrutiny because raw text generation models yield contradictory, sycophantic, and statistically ungrounded answers.
When I ran successive prompt iterations asking an unconstrained model how mid-market IT directors viewed cloud migration security, the persona shifted its risk tolerance completely between runs, praising the exact vendor it had dismissed ten minutes prior.
Translating vague editorial hunches into rigorous validation metrics without a research background usually leads to biased survey designs that confirm whatever the author already suspected. Stakeholders reject content angles backed only by intuition, demanding empirical proof and data distributions that creators cannot easily source from casual brainstorming. Without a reliable mechanism to generate consistent respondent behavior, creators are left choosing between expensive panels they cannot afford and unreliable chat transcripts they cannot defend.
Anatomy of a Virtual Cohort: Moving Past Vague AI Personas to Census-Level Data Grounding
Simulated audience surveys fail when built on unconstrained large language model personas because they lack joint probability distributions, resulting in incorrect correlations between features. A study on statistically accurate tabular data generation notes that because LLMs operate auto-regressively, generating data sequentially rather than holistically, they result in incorrect correlations between features, leading to the generation of unrealistic or statistically inconsistent values, especially categorical ones, thereby compromising the utility of synthetic data for downstream tasks.
When an unconstrained model writes a persona, it invents age, income, and occupation traits independently rather than respecting how those variables actually move together in the real world.
True audience simulation treats respondent generation as a constrained sampling problem across multi-dimensional microdata rather than a creative writing exercise for text generation models. To make a simulated cohort behave like a real reader base, the underlying generation model must be anchored to population models such as the U.S.
Census Bureau American Community Survey Public Use Microdata Sample file, which represents about 1 percent of the total U.S. population or approximately 1.3 million housing unit records and about 3 million person records, as noted by the U.S. Census Bureau. Grounding synthetic personas in these actual microdata files ensures that income levels correspond realistically to occupational categories and geographic tiers.
Ignoring demographic covariance distorts driver rankings and turns simulated research into a glorified guessing game. When we tested our remote work hardware questions against a population model constrained by real Census microdata rather than raw text generation, the response variance dropped immediately and eliminated the contradictory sentiment swings we saw earlier.
Research examining reference-distribution dependence in LLM-based synthetic persona data, published in an arXiv paper in August 2026, compares the joint distribution of 1,000,000 records with official statistics and finds a bias bound of 1.81 percentage points against resident-registration figures, demonstrating that reference-period alignment keeps synthetic error comparable to the margin of error of a traditional survey of roughly 2,900 respondents.
The Mechanics of Automated Questionnaires: Translating Content Questions into Empirical Data
Translating open-ended content questions into structured empirical surveys requires mapping qualitative editorial intent to closed-ended variables that a population model can evaluate consistently. When I drafted the questionnaire for our IT director software migration guide, my first instinct was to ask broad, open-ended questions about what features readers valued most.
That approach failed because an automated cohort cannot compute open text without drifting into generic praise; the responses came back with zero differentiation between the three software options we were testing.
To fix that, I had to break each editorial hypothesis down into discrete comparative choices and scale-rated preference vectors. Instead of asking what respondents felt about security, I configured the survey questions around specific operational trade-offs, such as downtime tolerance versus deployment speed, that could be mapped directly against the demographic attributes in the underlying microdata model. This transformation turned a vague content hunch into a testable instrument where every simulated respondent evaluated the exact same structured inputs.
Passing these structured questionnaires through a population model built on demographic microdata forces the synthetic respondents to react according to their assigned constraints rather than defaulting to agreeable answers. When the platform processed our remote work technology survey against the demographic variables, the resulting dataset exposed clear friction points around legacy system integration that our initial chat prompts had entirely glossed over.
Unpacking the Output: Statistical Distributions, Driver Rankings, and Respondent Concerns
Reading a synthetic dataset requires looking past the winning option to examine the underlying distributions and response variances. When our remote work technology survey finished running, the resulting output did not just hand us a single preferred software feature; it mapped the exact share of preference across distinct demographic segments.
That granular breakdown revealed that our second-choice software option actually performed best among IT directors in high-income metropolitan brackets, while the winning option dominated solely because of sheer volume from smaller enterprises.
Evaluating driver rankings within the generated report helped us separate core operational requirements from secondary nice-to-have features. The platform sorted the decision factors by statistical weight, showing that migration speed outweighed upfront licensing cost by a measurable margin for our target cohort. That ranking prevented our editorial team from wasting precious word count on cost arguments that our simulated audience had already flagged as secondary.
Reviewing the top respondent concerns surfaced specific technical objections that our initial outlining phase had completely missed. The dataset highlighted recurring friction around data sovereignty and legacy API compatibility, giving our writing team concrete friction points to address head-on in the guide. Instead of guessing what readers might worry about, we built the entire middle section of our content piece around answering those exact simulated objections.
Overcoming the Trust Deficit: Methodological Rigor and Bias Prevention in Synthetic Datasets
Trust in synthetic research data is earned by exposing the underlying population parameters rather than hiding the mechanics behind a black box. Stakeholders and skeptical editors naturally push back against simulated datasets, suspecting that the numbers are just manufactured hallucinations. When I presented our survey findings to our editorial director, the first question was whether the respondent distribution matched real-world behavioral traits or just mirrored generic internet chatter.
To defend the data, I pointed directly to the population parameters governing the simulation, showing how the constraints enforced realistic covariance across age, income, and occupation variables. That transparency transformed the conversation from an argument over whether AI can be trusted into a rigorous examination of sample weighting and demographic bounds. Recognizing that synthetic cohorts carry inherent margins of error keeps the analysis honest and prevents creators from treating modeled outcomes as absolute mathematical certainty.
Comparing synthetic error rates against traditional benchmarks helps ground expectations without overstating precision. Research examining reference-distribution dependence in LLM-based synthetic persona data, published in an arXiv paper in August 2026, compares the joint distribution of 1,000,000 records with official statistics and finds a bias bound of 1.81 percentage points against resident-registration figures, demonstrating that reference-period alignment keeps synthetic error comparable to the margin of error of a traditional survey of roughly 2,900 respondents.
Knowing those boundaries lets creators publish simulated data with clear caveats about its scope and limitations.
Integrating Empirical Simulation into SEO, GEO, and Content Production Workflows
Embedding simulated audience research into an active publishing workflow changes how teams plan and execute content clusters before a single word is drafted. Instead of writing an outline based on keyword search volume alone, our workflow now begins by running a structured survey to test reader intent and angle viability. That shift saved our team from investing weeks into drafting a remote work software guide that our target demographic would have scrolled right past.
Scaling this validation process across multiple content pieces relies on standardizing how research questions are translated into closed-ended variables. By connecting our editorial queries to a reliable population model rather than starting from scratch each time, we turned audience research from an expensive bottleneck into a repeatable pre-publishing check. When publishing deadlines are tight and human panels are out of reach, generating a structured dataset through a platform like MoeVox provides the empirical backbone needed to defend an editorial angle.
Do not publish a high-stakes content cluster until you have tested your primary headline angles against a simulated cohort of at least 1,000 respondents grounded in real demographic microdata.